[](https://github.com/tommy0103/obelisk/stargazers)
[](https://github.com/tommy0103/obelisk/releases)
[](LICENSE)
Past Claude Code, Codex, Kimi Code, and Pi sessions -- queryable by your agent, browsable by you.
## Two sides of the same index
Obelisk has two sides that share one SQLite index:
**Agent side** — the `obelisk` CLI owns the local runtime, while a separate
agent skill teaches coding agents how to search and query their session history.
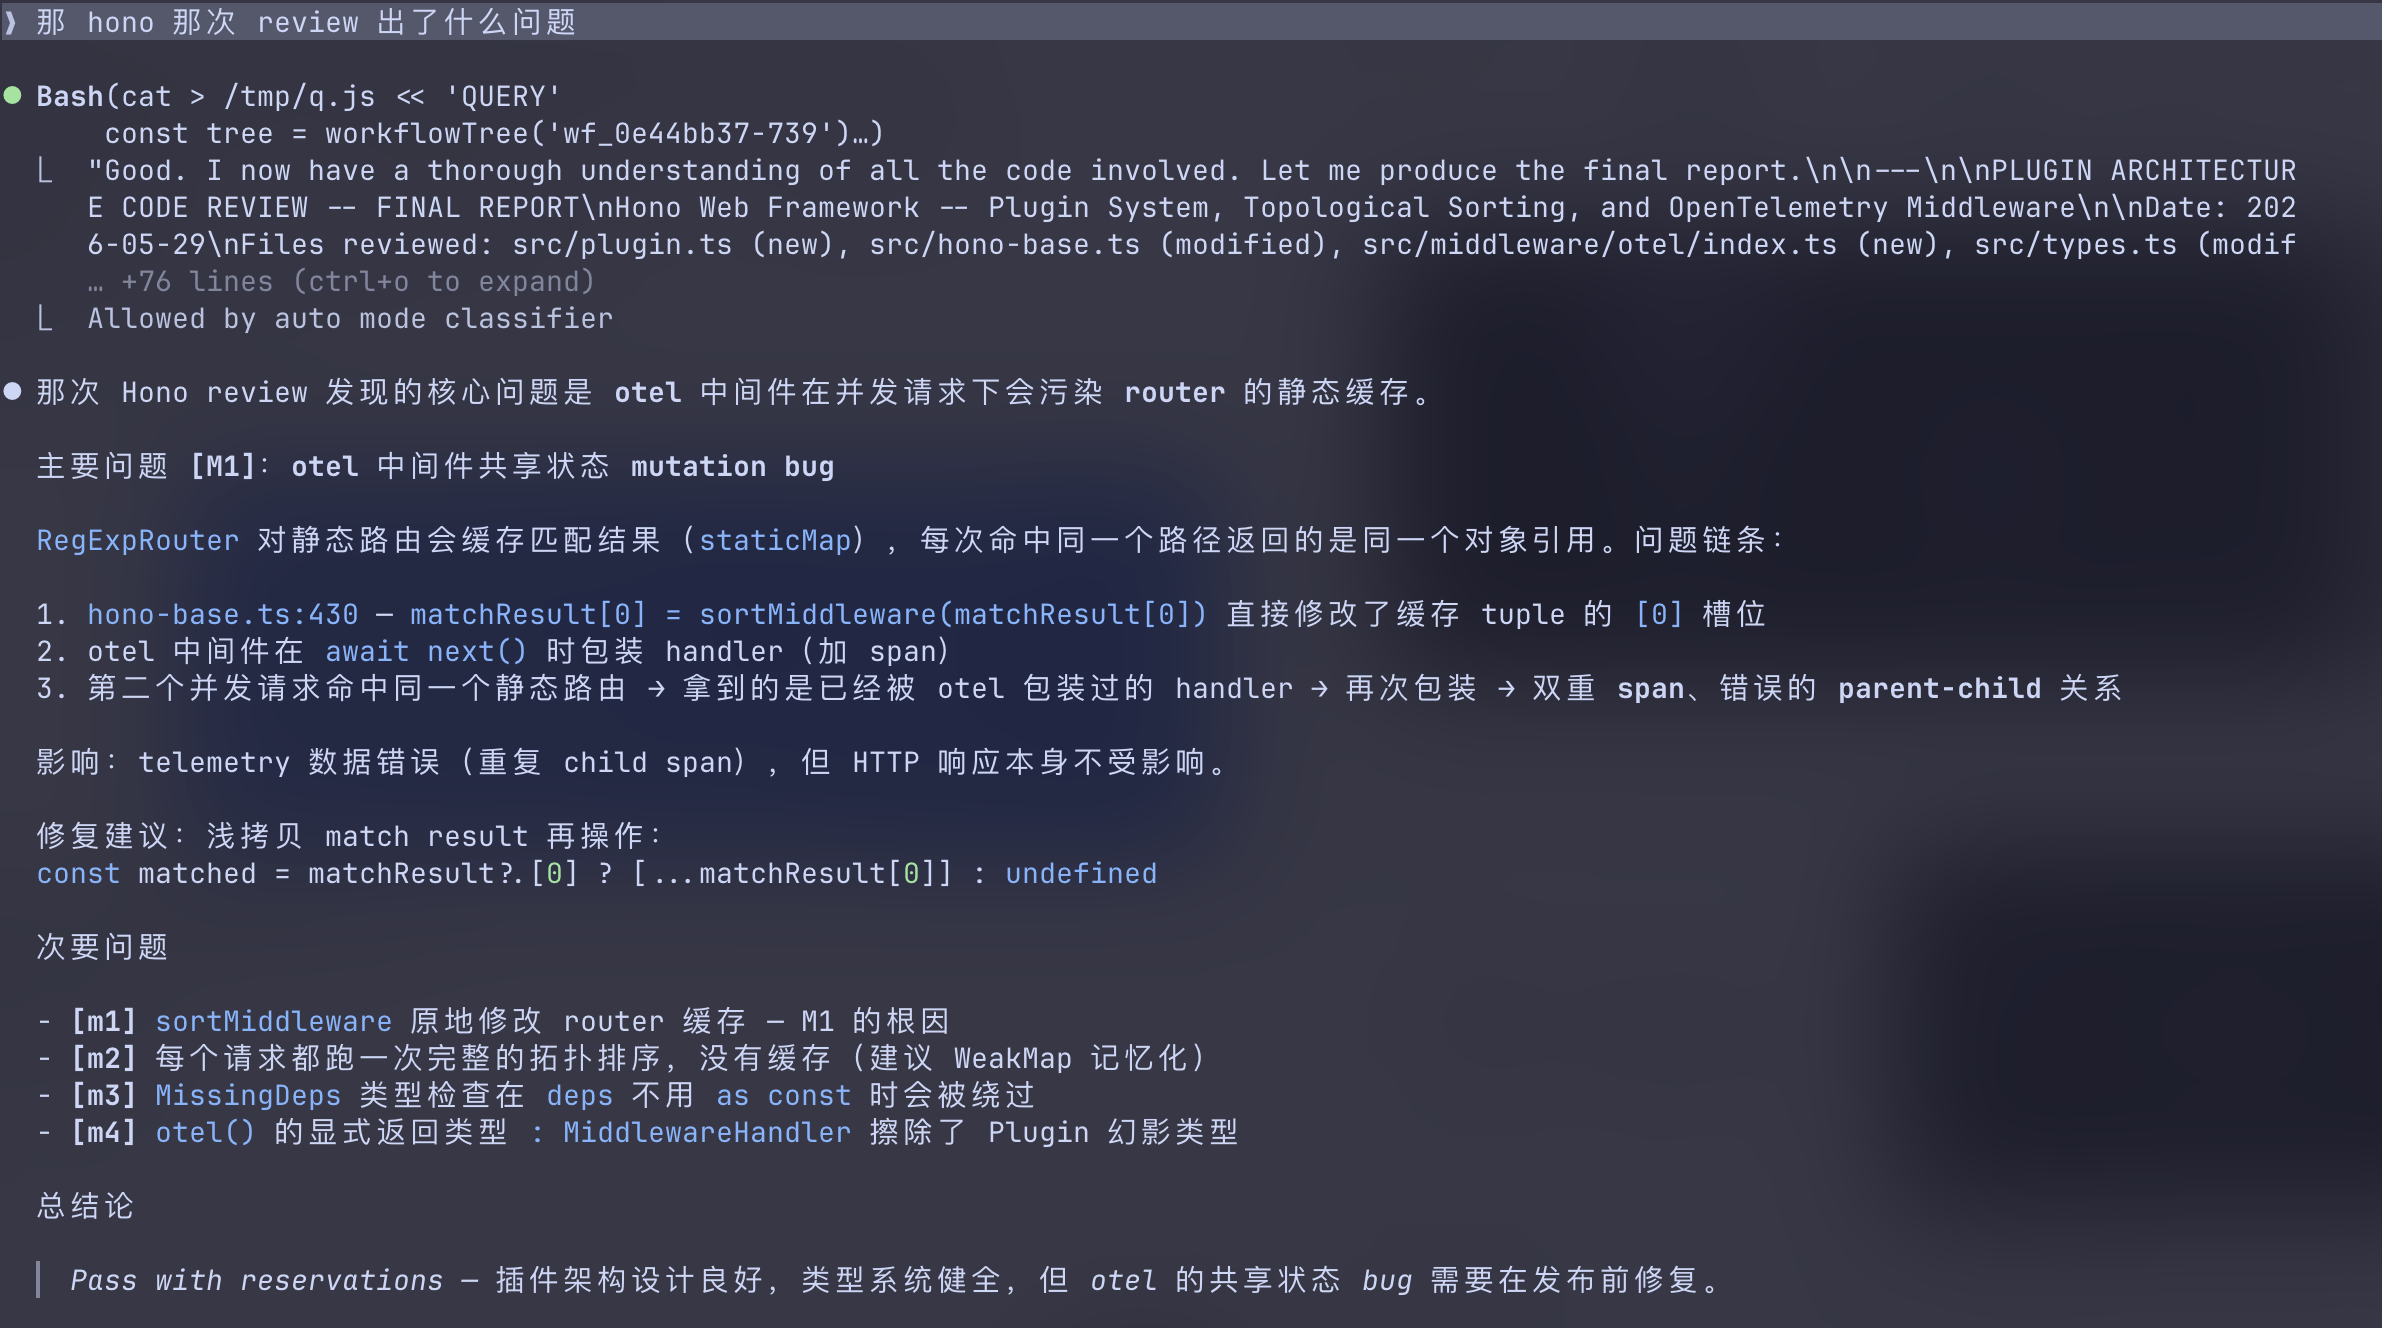
The agent writes JS queries, runs them locally, and answers in plain language.
**App side** — an Electron desktop app for humans to browse sessions, manage memories, view usage stats, and see weekly recap cards.
Both read from the same `~/.obelisk/obelisk.sqlite` database. The indexer reads Claude Code transcripts from `~/.claude/projects`, Codex transcripts from `~/.codex/sessions`, Kimi Code sessions from `~/.kimi-code/sessions` (or `$KIMI_CODE_HOME/sessions`), and Pi sessions from `~/.pi/agent/sessions`.
## Multi-provider support
Obelisk indexes every provider into the same SQLite schema instead of keeping separate databases. Rows carry a `source` value, and non-Claude IDs are provider-prefixed so they cannot collide.
Codex root threads become normal Obelisk sessions. Codex child threads are attached through the same `subagents` table when parent-thread metadata is available. Codex does not emit Claude-style workflow metadata, so workflow tables may be empty for Codex-only history.
Kimi session directories become one Obelisk session each. Main and child-agent
`wire.jsonl` streams are projected into the same messages, tools, summaries and
subagents tables. Undo/clear is handled as a full session replay, so retracted
wire records do not remain in the index.
Pi JSONL v1-v3 sessions are projected through the same provider contract. Pi's tree, branch summaries, compactions, durable leaf, retained checkpoint tail, custom messages, bash records, tool calls, token usage, and raw JSONL evidence stay inside the adapter; no Pi-specific database or renderer branch is needed. Active visibility follows Pi's own context rules: a retained tail replaces pre-compaction ancestors even when those physical entries still exist and bounds any later legacy compaction, while a legacy-only chain retains ancestors beginning at `firstKeptEntryId`. Missing parents form orphan branch roots, matching Pi's recovery behavior. Pi entries that the source explicitly superseded are stored as `inactive`: the app and normal agent queries omit them, while supported query helpers can include them with `includeInactive: true`. Display-suppressed or transport-only records remain `hidden` and are never returned by those helpers.
| Provider | Superseded-history support |
| --- | --- |
| Pi | Branch, leaf, and compaction state attests inactive history |
| Kimi Code | Undo/clear can attest supersession; preservation is a follow-up |
| Claude Code | The source does not attest rewind or current-leaf state |
| Codex | Sessions have no branching semantics |
Because Pi's explicit `--session-id` is project-local, Obelisk combines the header ID with a deterministic hash of the normalized header `cwd`; this keeps the identity stable across file moves and v1-v3 migration while allowing two projects to use the same custom ID. Replacement and deletion replay is provenance-aware, so stale session snapshots are retracted atomically; compaction and branch-summary model usage is included in usage totals.
For live app refresh, Obelisk watches the roots declared by every registered provider, including `~/.claude/projects`, `~/.codex/sessions`, `~/.kimi-code/sessions`, and `~/.pi/agent/sessions`. Codex's `session_index.jsonl` is used as lightweight title/update metadata during indexing, not as the message transcript source.
Pi chooses its session directory in this order: `--session-dir`, `PI_CODING_AGENT_SESSION_DIR`, `sessionDir` in settings, then the default under `~/.pi/agent/sessions`. Obelisk automatically follows absolute or `~`-prefixed environment/global settings and the project setting for Obelisk's launch cwd; a relative project setting is resolved against that cwd. CLI-only roots, relative environment/global settings, and project settings from another launch cwd cannot be inferred safely, so select the resolved directory in Obelisk **Settings** instead of letting Obelisk guess.
## Skill: agent-first retrieval
You can use obelisk like:
```
/obelisk 上次 auth bug 最后到底改了哪些文件,为什么这么改
/obelisk 这个文件最近在哪些 sessions 里被反复修改
/obelisk 找出最近失败的 tool calls,它们分别发生在哪些任务里
/obelisk 那个 review workflow 的 subagents 各自结论是什么
/obelisk recap this week
```
### Install
#### Let your agent install it (recommended)
The shortest path is to give the bootstrap guide directly to a coding agent
with shell access. Paste this as a prompt into Claude Code, Codex, or another
agent — not into your terminal:
```text
Install Obelisk by fetching and following this guide:
curl -fsSL https://raw.githubusercontent.com/tommy0103/obelisk/main/SKILL.md
```
The agent will ask before changing your machine, install and verify the CLI,
then ask whether the formal `/obelisk` skill should be installed for the current
project or globally. The bootstrap guide is only for one-time setup; it is not
the query skill itself.
#### Install manually
Obelisk requires Node.js 22.13 or newer. Install the platform-neutral CLI:
```bash
npm install --global @obelisk-apps/cli
obelisk --version
```
On macOS, Linux, or WSL, the CLI-only installer is equivalent:
```bash
curl -fsSL https://raw.githubusercontent.com/tommy0103/obelisk/main/install.sh | sh
```
Then install the agent skill:
```bash
obelisk install
```
`obelisk install` delegates to the standard skills installer for
`tommy0103/obelisk-skill`.
Then in any Claude Code session:
```
/obelisk
```
First run builds the index (~5 seconds for 100 sessions). After that it rebuilds incrementally.
### How it works
```
You ask a question
↓
Agent writes a JS query against the SQLite index
↓
Runs it via obelisk --query